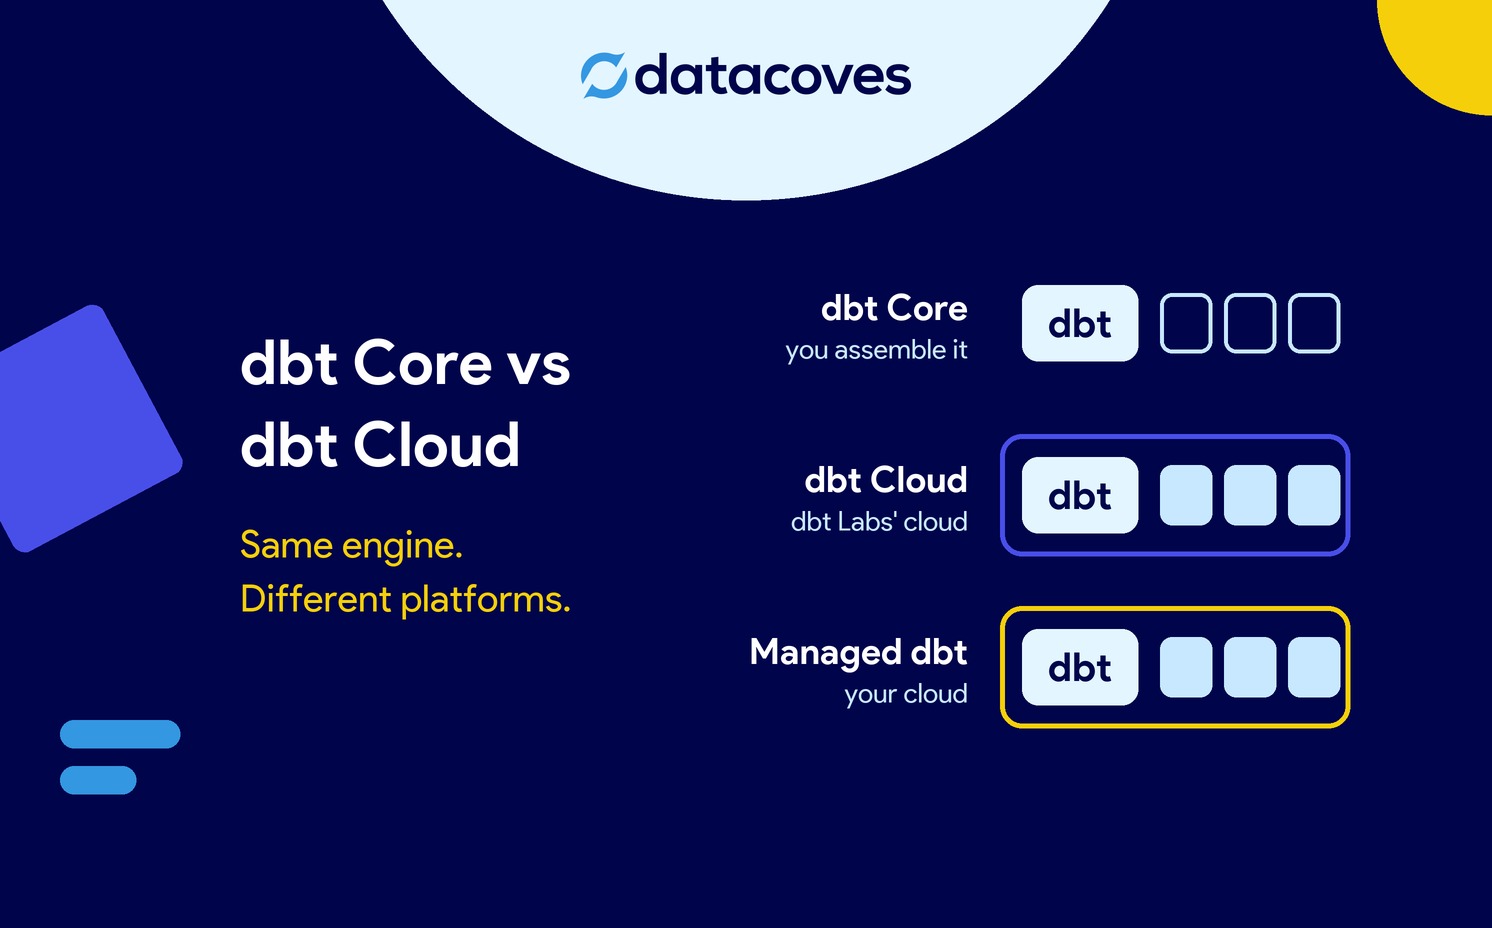
- dbt Core, renamed dbt v1 in September 2026, and dbt Cloud, now the dbt Platform, run the same transformation engine. The difference is who operates the IDE, the scheduler, the CI pipeline, and the secrets.
- dbt Core is free to run. Your team builds and maintains the orchestration, CI/CD, developer environments, and secrets management that production requires.
- The dbt Platform’s Starter plan is $100 per developer per month, capped at five seats and one project, with no SSO. Past any of those three limits, you’re in an Enterprise contract.
- Four things meter separately on the dbt Platform: model builds past your plan’s allowance, Semantic Layer queried metrics, dbt State at $0.094 per daily active target table, and dbt Wizard tokens.
- Managed dbt platforms like Datacoves run the same engine with orchestration, CI/CD, and AI tooling already assembled, as SaaS or inside your own cloud account. Snowflake also runs dbt natively, which gives enterprises four platform options rather than two.
dbt Core and dbt Cloud both run the same transformation engine. The difference is in who operates everything else: the IDE, the scheduler, the CI pipeline, the secrets.
dbt Core, renamed dbt v1 at dbt Summit in September 2026, is the Apache 2.0 command-line tool. It’s free, runs anywhere, and leaves orchestration, CI/CD, developer environments, and secrets management to your team. dbt Labs has since consolidated its engines into dbt v2, with dbt-oss as the Apache 2.0 subset of it.
dbt Cloud, now the dbt Platform, is the managed SaaS built on the same engine. It adds a browser IDE, a job scheduler, CI/CD, a hosted semantic layer, and metadata APIs. Setup is faster, tooling is more constrained, and several things bill by usage on top of seats.
Managed dbt platforms like Datacoves run dbt as SaaS or inside your own cloud, with the IDE, orchestration, CI/CD, and secrets management already in place and managed for you.
The right choice depends on your team’s engineering capacity, security requirements, and how much infrastructure you want to own.
What Are dbt Core and dbt Cloud Now?
dbt Core and dbt Cloud both run the same transformation engine. The difference is in who operates everything else: the IDE, the scheduler, the CI pipeline, the secrets.
dbt (data build tool) is a transformation framework for building, testing, and deploying SQL-based data models. For most of its life there were two things to compare, the free CLI and the hosted platform. September 2026 made it four names, so here is what each one means today.
dbt Core still exists. It was renamed dbt v1, and its current release, v1.12, has active support through July 15, 2027. All three engine builds are free to download and run; only dbt v1 and dbt-oss are open source. For adapter coverage, migration steps, and what to do with an existing dbt Core project, see our breakdown of dbt 2.0 and dbt Fusion.
A managed dbt platform isn’t on that list, and that’s the point: it’s orthogonal to it. Datacoves runs dbt v1 or dbt v2 as SaaS or inside your own cloud account, so the engine question and the platform question stop being the same decision. Teams can move one project to v2 while the rest stay on v1, without renegotiating who hosts the IDE or who runs the scheduler.
The engine is the part everyone shares. Everything else is a platform decision.
Get the free ebook: dbt for the Enterprise
Four ways to run dbt at enterprise scale: the dbt platform, dbt on Snowflake, a DIY stack, and managed dbt in your own cloud. Compare them on cost, security, and what each one leaves you to build.
Get the PDF
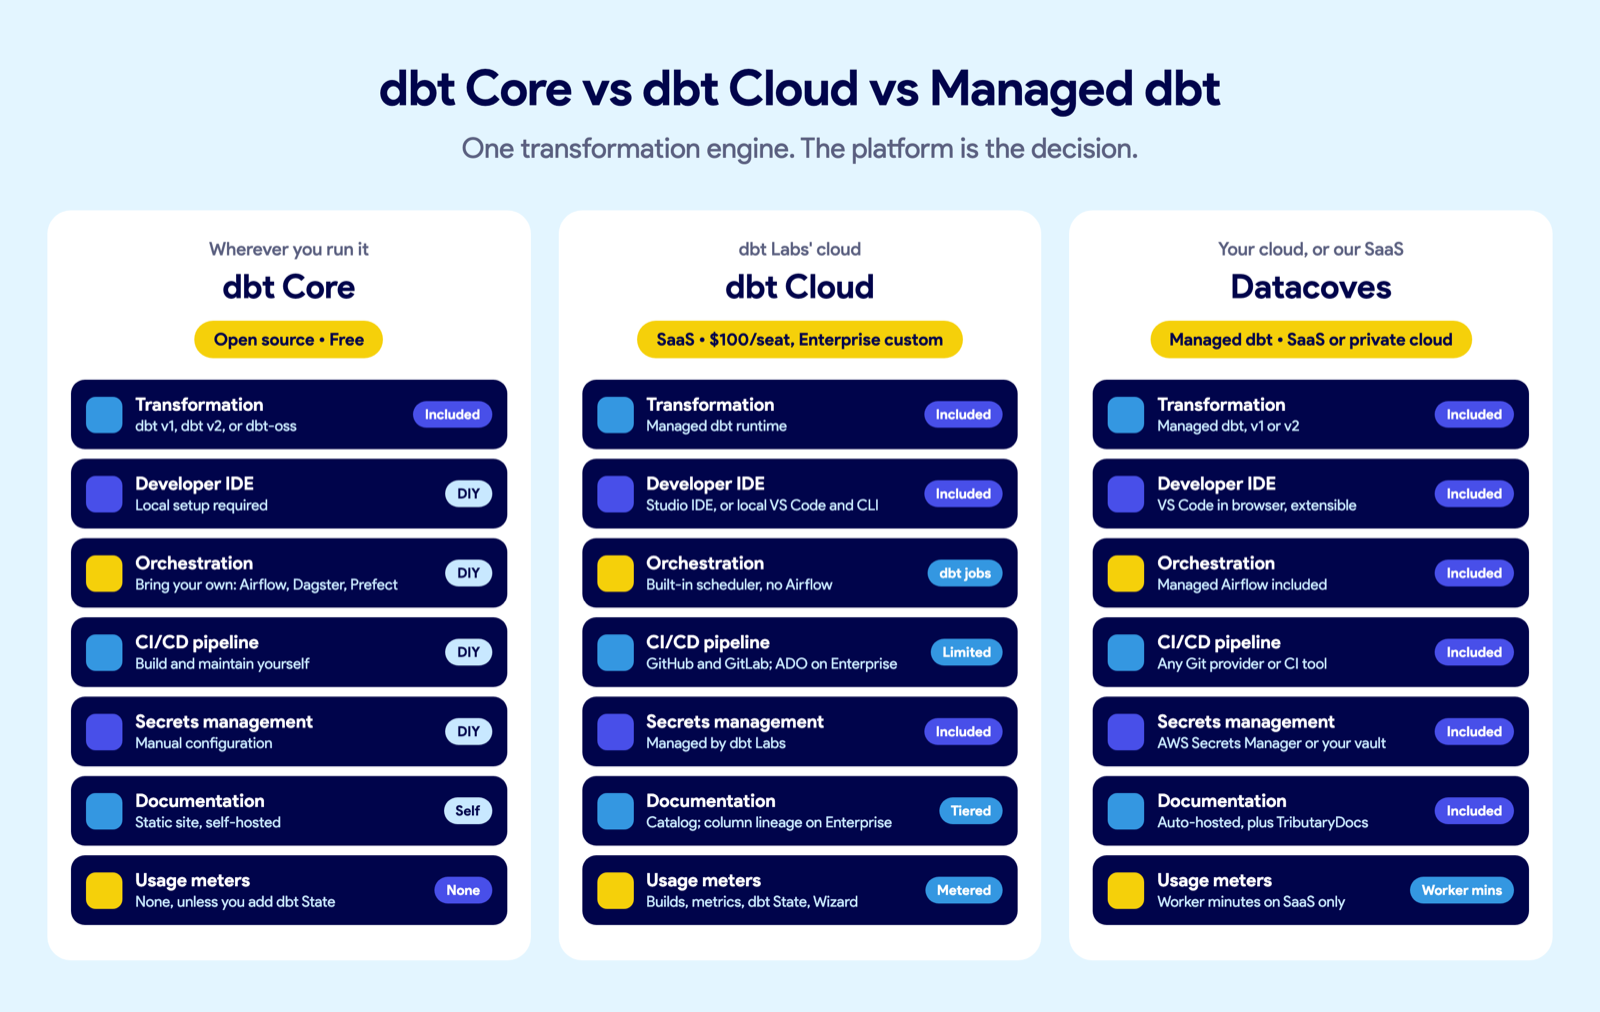
How dbt Core and dbt Cloud Compare at a Glance
The table below covers the key decision points. Sections that follow go deeper on each one.
Developer Environment: IDE and Setup
dbt Core
With dbt Core, every developer sets up their own environment. That means installing dbt, configuring a connection to the warehouse, managing Python versions, and handling dependencies like SQLFluff or dbt Power User. On paper, straightforward. In practice, setup can take anywhere from a few hours to several days depending on the developer’s experience and the organization’s IT constraints.
Pre-configured company laptops often ship with software that may conflict with dbt. Proxy settings, restricted package registries, and corporate firewall rules add friction before a developer writes a single line of SQL.
The upside is full control. Teams can use any IDE they prefer: VS Code, Cursor, PyCharm, or whatever fits their workflow. There are no constraints on tooling choices, and developers who already have strong local environment preferences can keep working the way they work best.
The maintenance challenge grows with team size. Every dbt version upgrade needs to happen in sync across all developers. On a small team that’s manageable. On a team of 20 or more, someone is always on a different version, and those mismatches cause inconsistent behavior, failed CI runs, and debugging sessions that should never have happened. Organizations that skip upgrades to avoid the coordination cost accumulate technical debt that gets harder to unwind over time.
dbt Cloud
dbt Cloud’s web IDE lets developers log in through a browser and start writing SQL without installing anything locally. No Python, no CLI, no profiles.yml. For analytics engineers who are new to dbt or unfamiliar with command-line tools, this is a genuine advantage.
The trade-off is flexibility. The web IDE does not support VS Code extensions or custom Python libraries. Teams that rely on SQLFluff configurations, internal Python packages, or warehouse-specific extensions like the Snowflake VS Code plugin will find it limiting.
dbt Cloud also offers a CLI option that lets developers work locally in VS Code while dbt Cloud handles compute. Many teams end up running both: newer analysts in the web IDE, senior engineers on the CLI. But the CLI path reintroduces the local environment problems the web IDE was supposed to solve. SQLFluff versions, Python dependencies, and VS Code extensions still need to be installed and kept in sync across every developer’s machine. On larger teams, that version drift shows up quickly.
Managed dbt
Datacoves provides VS Code running in the browser, fully managed and pre-configured. Developers get the VS Code they already know, without any local installation. Warehouse connections, Git configuration, Python environments, and tooling like SQLFluff are set up out of the box.
Where Datacoves differs from dbt Cloud’s web IDE: the environment is fully extensible. Teams can install any VS Code extension, add internal Python libraries, and configure the workspace to match their standards. Organizations with proprietary packages or warehouse-specific tooling can bring those into the environment without workarounds.
Onboarding a new developer is a matter of clicks, not days. When dbt or a dependent library needs an upgrade, Datacoves handles it. Developers work in a consistent, current environment without touching it.
The engine upgrade is handled the same way. dbt v2 runs on Datacoves alongside dbt v1.12, and so does the official dbt VS Code extension, so a team can move one project to v2 while the rest stay on v1 until their adapters and packages are ready. dbt v2’s license permits managed platforms to distribute it, which Fusion’s Elastic License 2.0 did not, so this stopped being a licensing question when v2 reached GA in September 2026.
Scheduling and Orchestration
dbt Core
dbt Core has no built-in scheduler. Teams choose their own orchestration tool, with Apache Airflow being the most common choice in enterprise environments. This gives full flexibility: you can connect ingestion, transformation, and downstream activation steps into a single pipeline, trigger internal tools behind the firewall, and orchestrate anything in your stack.
That flexibility comes with real cost. Airflow is not simple to operate. Running it reliably at scale requires Kubernetes knowledge, careful resource management, and dedicated engineering attention. A production-grade Airflow setup with separate local development, testing, and production environments is a multi-month investment for most teams. When you add advanced features like external secrets management, alerting, and DAG version control and the scope grows further.
Teams that underestimate this often end up with a fragile single-environment setup or become dependent on the key people who understand how everything works until it doesn’t.
dbt Cloud
dbt Cloud includes a built-in job scheduler with a clean UI for configuring run frequency, retries, and alerts. For teams that only need to run dbt on a schedule, it works well and requires no additional tooling.
The limitation becomes clear when pipelines grow beyond dbt. If you need to connect an ingestion step before transformation, trigger a downstream tool after a model run, or orchestrate anything outside dbt’s scope, the built-in scheduler is not enough. dbt Cloud offers an API to trigger jobs from an external orchestrator, but that adds integration overhead and means maintaining two systems.
Enterprise teams with existing Airflow infrastructure often end up running dbt Cloud jobs triggered by Airflow anyway, which raises the question of why they’re paying for a scheduler they’re not using.
Managed dbt
Datacoves includes Managed Airflow as part of the platform. Two environments come pre-configured: a personal Airflow sandbox for each developer to test DAGs without affecting anyone else, and a shared Teams Airflow for production workflows. Both are pre-integrated with dbt and Airflow, so DAG creation for dbt runs is straightforward without custom operators or glue code.
On a private deployment, because Airflow runs inside your own cloud alongside dbt, it can reach internal systems, on-premise databases, and tools behind the corporate firewall. End-to-end pipelines that include ingestion, transformation, and activation steps all run in one orchestration layer without external API calls or cross-network dependencies.
Spinning up additional Airflow environments takes minutes, so enterprises can provision separate development, testing, and production environments without infrastructure work. Teams with complex testing requirements or multiple projects can have as many environments as they need.
Datacoves also supports simplified DAG creation using YAML, reducing the Python burden on teams that are primarily SQL-focused.
dbt Cloud covers transformation and scheduling, but it does not cover orchestration of the broader pipeline. Teams still need to run and maintain Airflow or another orchestrator alongside it.
CI/CD and DataOps
dbt Core
dbt Core gives teams complete control over their CI/CD pipeline. Any Git provider works: GitHub, GitLab, Bitbucket, Azure DevOps, or internal systems like Bitbucket Server. Any CI tool works too: GitHub Actions, GitLab CI, Jenkins, CircleCI, or whatever the organization already runs behind the firewall.
That flexibility is genuinely valuable for enterprises that have invested in internal tooling. A team on Jenkins with Bitbucket can build a world-class dbt CI pipeline without compromising on either tool.
The cost is setup time. Docker images need to be built and maintained with the right dbt version, SQLFluff configuration, and Python dependencies. CI runners need to be provisioned and kept current. Notification routing to Slack, MS Teams, or email needs to be configured separately. None of this is insurmountable, but it adds up fast and requires platform engineering skills that not every data team has.
Developers also have no way to run CI checks locally before pushing, which means failed CI runs often require multiple commits to fix, slowing down the feedback loop.
dbt Cloud
dbt Cloud has built-in CI that automatically triggers a run when a pull request is opened. It builds only the modified models and their downstream dependencies in a temporary schema, posts results back to the PR, and cleans up when the PR is merged or closed. For teams on GitHub or GitLab, this works well and requires minimal configuration.
The constraints appear quickly in enterprise contexts. Automated CI jobs need a native Git integration, which means GitHub or GitLab on any plan, or Azure DevOps on Enterprise and Enterprise+. Teams on Bitbucket, AWS CodeCommit, or an internal Git server connect by Git clone and trigger jobs through the Administrative API instead, which is custom integration work in the place the platform was meant to remove it.
Customization is also limited. The CI pipeline runs dbt checks. Adding custom steps, internal validation scripts, or governance checks outside of what dbt Cloud natively supports requires workarounds. Teams with mature DataOps practices often find the built-in CI too rigid to fit their standards.
Managed dbt
Datacoves provides pre-built CI/CD pipelines that work with any Git provider and any CI tool, including Jenkins and internal enterprise systems behind the firewall. The pipeline comes configured with dbt testing, SQLFluff linting, dbt-checkpoint governance checks, and deployment steps out of the box.
Developers can run the same CI checks locally before pushing changes, which catches issues before they reach the pipeline and dramatically reduces the back-and-forth of fixing failed CI runs. When the local check passes, the CI check passes.
Because the pipeline is fully customizable, teams can add any step they need: internal approval workflows, custom validation scripts, notifications to MS Teams, or integration with ticketing systems like Jira. There are no constraints on providers or tools.
State Management: Slim CI and dbt State
Rebuilding models that haven’t changed is where most warehouse spend leaks, and there are now two ways to stop it that cost very different amounts.
Slim CI and deferral are free and work on every dbt version. You store the production manifest.json somewhere, compare against it with state:modified+ or source_status:fresher+, and build only what moved. The work is in the plumbing: persisting the artifact, retrieving it at the start of each run, and accepting that a whitespace edit counts as a change. On dbt Core that plumbing is yours to build. On the dbt Platform the PR job handles it for you. Datacoves ships it as a pre-built CI/CD template, and dbt-api pushes and pulls the artifacts so deferral works without an S3 bucket someone has to maintain.
dbt State is the paid alternative. It keeps shared state across jobs in an environment, diffs compiled SQL so comments and whitespace don’t trigger a rebuild, and skips, clones, or reuses what hasn’t changed. dbt Labs reports an average 15 to 30% reduction in warehouse compute. It bills at $0.094 per daily active target table, where a target table is any model, test, seed, or snapshot it reuses in a day. A model with two tests is three. It’s sold with no seats and no minimums and runs against self-hosted dbt or a managed platform, so adopting it doesn’t mean adopting the whole dbt Platform.
Get Slim CI working first, because it’s free and covers most of the waste. Then price dbt State against the warehouse spend it would remove, at your project’s size today and at the size you expect in three years. Our breakdown of the four ways to manage dbt state compares all of them side by side, including Orchestra’s open-source Sao Paolo and warehouse-native options like Snowflake dynamic tables.
Semantic Layer
dbt Core
dbt Core has no built-in semantic layer. Teams choose from several mature options depending on their warehouse and BI tool preferences.
Cube.dev is the most widely adopted open-source choice. It provides a headless semantic layer with its own API, caching, and broad BI tool support. Lightdash and Omni are strong alternatives that integrate tightly with dbt models and work well for teams that want metric definitions to live close to their transformation code.
For Snowflake users, the dbt_semantic_view package lets teams manage Snowflake Semantic Views directly from their dbt project. Metrics defined this way live in the warehouse itself and are accessible to any tool connected to Snowflake, without routing data through a third-party service.
The open-source path requires more setup and maintenance than a managed semantic layer, but it gives teams full control over where metrics are defined, how they are served, and which tools consume them.
dbt Cloud
dbt Cloud includes a hosted semantic layer powered by MetricFlow. MetricFlow was acquired from Transform in 2023 and open-sourced under Apache 2.0 at Coalesce 2025. The engine itself is now free to use. The hosted service in the dbt Platform is a paid feature available on Starter plans and above. Usage is metered by queried metrics per month, and result and declarative caching require Enterprise or Enterprise+, which is the feature that keeps repeated questions off the warehouse.
Supported BI integrations include Tableau, Power BI, Excel, Google Sheets, Hex, Mode, and Omni. Power BI reached general availability; Sigma is the one still in preview. Anything without a native integration connects over JDBC, ADBC, GraphQL, or the Python SDK.
Warehouse support is the harder constraint. The Semantic Layer runs on Snowflake, BigQuery, Databricks, Redshift, Postgres, and Trino, and Microsoft Fabric is not among them. dbt Labs also states plainly that client data passes through the Semantic Layer on the way back from the data warehouse, encrypted and cached only ephemerally. For organizations with strict data residency requirements, that architecture is what decides it, regardless of plan.
The spec settled down this year. dbt Labs modernized the MetricFlow YAML spec so a semantic model is declared on the model it describes rather than as a standalone top-level resource, and the latest spec now runs on dbt v1.12, dbt v2, and the platform’s v1 Latest release track. One gap is worth knowing before you migrate: cross-project references under dbt Mesh still require the legacy spec. dbt Labs has also joined the Open Semantic Interchange initiative alongside Snowflake, Salesforce, BlackRock, and others to work toward an open standard, though no engine is fully OSI compliant yet.
Managed dbt
Datacoves does not run a semantic layer of its own, and does not tie you to one. Metrics are defined in your dbt project, and you choose what serves them: Snowflake Semantic Views through the dbt package above, so the warehouse answers any tool connected to it; a serving layer your team runs, such as Cube.dev or Lightdash; or a BI tool with one built in, such as Omni.
MetricFlow fits the same way. The engine is Apache 2.0 and runs wherever dbt runs, so you define metrics on the latest spec in your Datacoves environment and query them with the dbt-metricflow CLI, with no queried-metric meter. What the dbt Platform’s hosted Semantic Layer adds is a managed API for BI tools to query. Datacoves does not host that API, which is why the choice above is the one to make.
The OSI standard is still developing. Until compliance is widespread across tools, flexibility is the lower-risk position. Datacoves gives you that flexibility without requiring a bet on any single vendor’s implementation.
Documentation and Lineage
dbt Core
dbt Core generates documentation automatically from your project: model descriptions, column definitions, tests, and a DAG showing upstream and downstream dependencies. You run dbt docs generate to build the static site and dbt docs serve to view it locally.
The limitation is hosting. dbt Core produces a static artifact. Your team is responsible for serving it somewhere accessible, keeping it updated after each run, and managing access controls. Many teams end up with stale docs because the pipeline to publish and refresh them is never properly automated. As projects grow across multiple teams and hundreds of models, the static site format also becomes a constraint. Navigation slows down, search is limited, and there is no real multi-project support.
dbt Cloud
dbt Cloud hosts your documentation automatically and updates it after each production run. On Starter plans, teams get dbt Catalog rather than the static dbt Docs experience. The features that matter most at enterprise scale, including column-level lineage, multi-project lineage, and project recommendations, are gated behind the Enterprise plan.
Snowflake now provides native lineage, column level included, directly in the warehouse. That covers a large share of what teams historically needed a separate docs tool for, and it’s worth checking before you price a plan around lineage alone.
Managed dbt
Datacoves automates documentation generation and hosting as part of the CI/CD pipeline. Docs are updated on every merge without manual intervention, and the hosted site is available to your full team inside your private environment at no additional cost.
For teams that have outgrown the static dbt docs experience, Datacoves also offers TributaryDocs. Unlike the default dbt docs site, TributaryDocs is a client-server application, which means it scales to enterprise-sized projects without the performance and navigation limitations of a static site. It includes an MCP server, enabling AI tools to query your documentation directly and making your data catalog part of your AI-assisted development workflow.
Datacoves customers can also connect external catalogs like Alation or Atlan, or use the catalog built into their warehouse. Snowflake, for example, includes native column-level lineage directly in the platform.
APIs and Extensibility
dbt Core
dbt Core produces a set of artifacts after every run: manifest.json, catalog.json, and run_results.json. These files contain your full project metadata and are the foundation for any custom tooling, observability integrations, or downstream automation you want to build.
Because dbt Core is open source, you have complete access to these artifacts and full control over how you use them. The tradeoff is that everything is self-managed. Parsing artifacts, building pipelines around them, and integrating with other systems requires custom engineering work that your team owns and maintains.
dbt Cloud
dbt Cloud exposes a set of APIs including the Discovery API for metadata queries, the Administrative API for managing jobs and environments, and webhooks for event-driven automation. These are well-documented and cover most standard integration scenarios.
The limitations show up at the edges. CI/CD integrations are constrained to supported Git providers. Some API capabilities are plan-gated, with full access requiring Enterprise. Teams building complex internal tooling or integrating with systems outside dbt’s supported ecosystem may find the platform less flexible than working directly with dbt Core artifacts.
Managed dbt
Datacoves runs dbt Core, so all native artifacts are available with no restrictions. Teams can build against manifest.json and run_results.json directly, integrate with any internal system, and use any CI tool or Git provider without platform constraints.
Datacoves also provides dbt-api, which enables pushing and pulling artifacts programmatically. This is particularly useful for slim CI, where only changed models are tested, and for deferral, where development runs reference production state without rebuilding the entire project.
On the orchestration side, Datacoves exposes the Airflow API, giving teams full programmatic control over their pipelines. This enables event-driven architectures using Airflow datasets, where DAGs trigger based on data availability rather than fixed schedules. Datacoves also uses run_results.json within Airflow to enable retries from the point of failure, so when a model fails mid-run, the DAG resumes from that model rather than restarting the entire pipeline.
For teams that want API-driven metadata beyond what dbt Core artifacts provide, TributaryDocs exposes an MCP server that makes your documentation and lineage queryable by AI tools and external systems.
AI and LLM Integration
dbt Core
dbt Core has no built-in AI capabilities. Teams can integrate any AI tool they choose by connecting it to their local development environment. VS Code extensions like GitHub Copilot, Cursor, or any MCP-compatible client can work alongside dbt Core projects with full access to your codebase.
The flexibility is real, but so is the setup overhead. Each developer configures their own AI tooling independently, which means inconsistent experiences across the team and no centralized control over which models or providers are in use.
dbt Cloud
dbt Wizard, which replaced dbt Copilot, is the AI agent built into the dbt Platform, Wizard Desktop, and the CLI. It generates documentation, tests, semantic models, and SQL from the context of your dbt project, and it ships with dbt’s own MCP server and agent skills out of the box. Custom MCP servers can be added alongside them.
Model choice is wider than it was. dbt-managed inference runs on OpenAI by default, with Anthropic and open-weight models available, and bring-your-own-key covers OpenAI, Anthropic, and Azure AI Foundry inside the platform, with AWS Bedrock, Google Gemini, Snowflake Cortex, and Databricks available when you run the CLI.
The billing is the part to plan for. Wizard bills per token at each model provider’s rate when dbt Labs manages the inference, and your provider bills you directly on BYOK. Credits are per account and shared across all users: Developer and Starter get $100 for a 30-day trial, Enterprise includes $100 a month, and Enterprise+ includes $200 a month. Past the included credits, usage draws from your consumption pool until it hits your spend limit. BYOK sidesteps the metering entirely, which for most enterprises with an existing model contract is the reason to use it.
For organizations whose security team has approved one specific provider, the question to settle early is whether that provider is on the managed list or needs BYOK, and which of the two your plan supports.
Managed dbt
Datacoves supports any copilot or LLM your organization has approved. Claude Code, GitHub Copilot, OpenAI Codex CLI, Gemini CLI, and Snowflake Cortex CLI all run inside the managed VS Code environment, billed by whichever provider you already have a contract with. The official dbt VS Code extension is supported too. Nothing here is metered by Datacoves.
Because the environment is a real VS Code workspace, any MCP server is a configuration choice. Snowflake’s MCP server, TributaryDocs’ MCP server, dbt’s own, or an internal one your team wrote all connect the same way.
Model choice and tool choice are the easy half. The harder problem is that an agent with warehouse access and no agreed definitions will confidently answer a question three different ways. Atlas is the agreement layer Datacoves built for that. A question gets settled once by the people who own it, and the result becomes a Definition of Record: plain English, versioned, attributed, and changed only through a reviewed change request. Every AI tool then reads those definitions over MCP, read-only and entitlement-checked, so dbt Wizard, Claude, and your own coding agents answer from the definition the business approved rather than from whatever they infer off column names. The Atlas explainer post walks through a worked example. Atlas is additive to whichever semantic layer you run, and it feeds dbt’s, Snowflake’s, or an open standard equally well.
For organizations in regulated industries, provider choice is a compliance requirement rather than a preference, and governed definitions are what make an agent’s answer defensible once it has one.
Security and Compliance
dbt Core
dbt Core has no built-in security controls. All security decisions sit with your team: where the environment runs, how credentials are managed, who has access, and how secrets are stored. For teams with the engineering capacity to implement this properly, that is complete flexibility. For everyone else, it is undifferentiated heavy lifting.
The most common gaps are secrets management, environment isolation, and consistent access controls across developers. These are solvable problems, but solving them requires deliberate investment and ongoing maintenance.
dbt Cloud
dbt Cloud is a SaaS product. Your data stays in your warehouse, but your code, metadata, and credentials pass through dbt Labs infrastructure. For many teams that is an acceptable tradeoff. For organizations in regulated industries such as pharma, healthcare, finance, and government, it often is not.
dbt Cloud offers SSO, role-based access control, and SOC 2 Type II compliance. SSO, RBAC, and SCIM start at Enterprise, so a Starter team that gets an SSO requirement from its security review is moving tiers rather than toggling a setting. PrivateLink and IP restrictions are Enterprise+. Hybrid Projects on Enterprise+ runs dbt execution on a dedicated cloud account while the IDE, scheduler, and Catalog stay in dbt Labs’ cloud, so teams that need the entire development and orchestration environment inside their own network perimeter don’t get there on any plan.
Managed dbt
Datacoves can be deployed in your private cloud account. Your code, your credentials, your metadata, and your pipeline execution all stay inside your own network. There is no VPC peering required and no data transiting a third-party SaaS environment.
Datacoves integrates with your existing identity provider via SSO and SAML, connects to your secrets management system such as AWS Secrets Manager, and supports your organization’s logging and audit requirements. Security controls are not bolt-ons, they are part of the deployment architecture from day one.
For organizations in regulated industries, this is the architecture that passes security reviews without exceptions. You are not asking your security team to approve a SaaS vendor touching your pipeline. You are showing them that everything runs in your own account, under your own controls.
Total Cost of Ownership
dbt Core
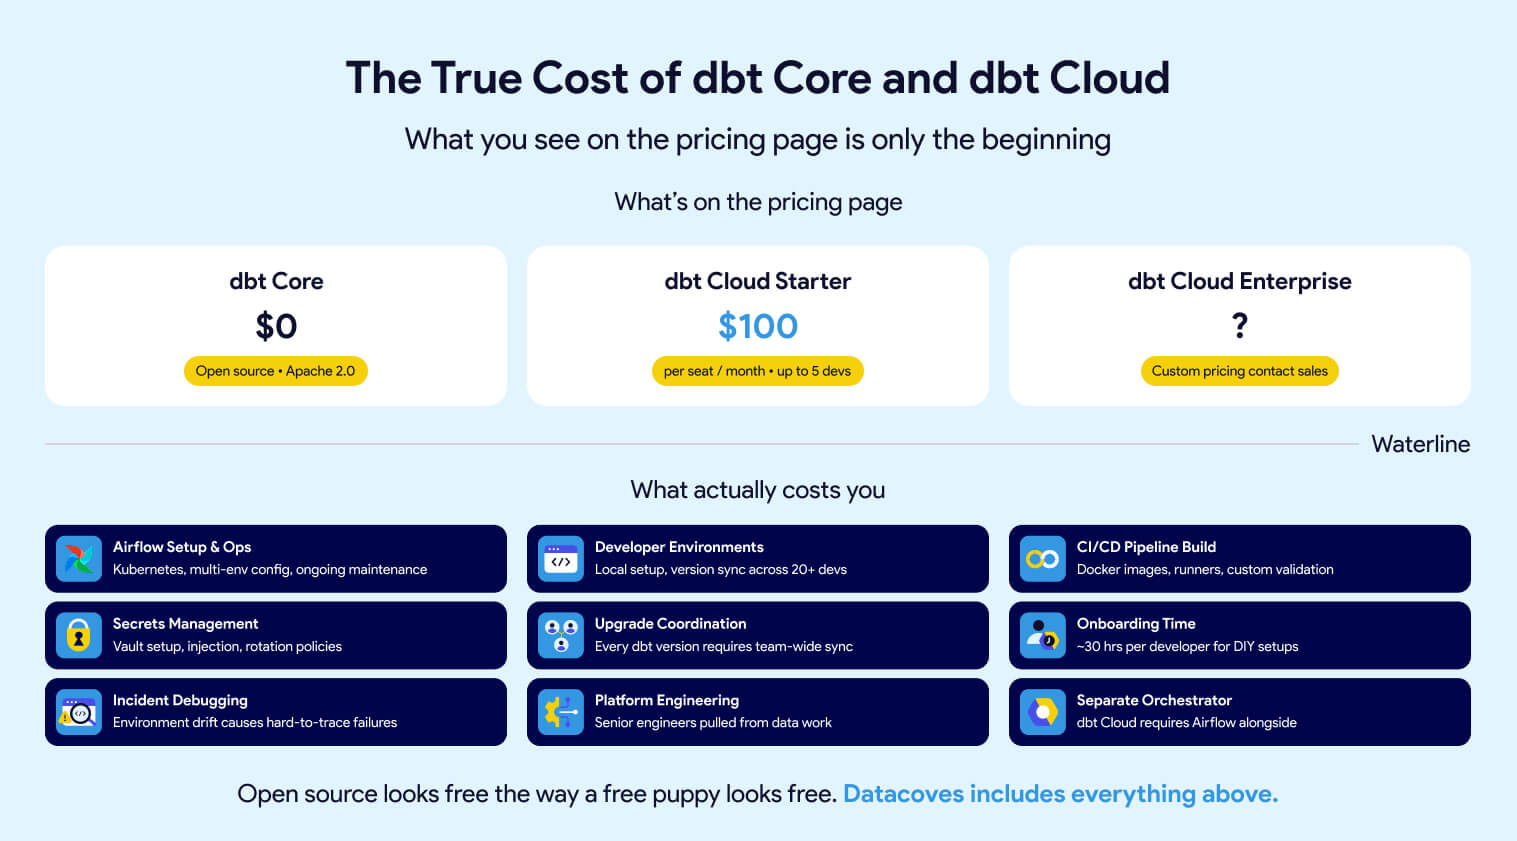
dbt Core is free. The platform it needs is not. A team that builds its own platform on dbt Core needs to provision and maintain developer environments, stand up and operate Airflow, build CI/CD pipelines, manage secrets, handle upgrades, and onboard every new developer into a custom setup.
That work falls on your most senior engineers. It is not a one-time cost. Every version upgrade, every new team member, and every incident that traces back to environment inconsistency is time your team is not spending on data products. Open source looks free the way a free puppy looks free.
dbt Cloud
dbt Cloud starts at $100 per developer seat per month on the Starter plan, which includes five seats, one project, 15,000 model builds, and 5,000 queried metrics, and leaves out SSO. Enterprise and Enterprise+ are custom-priced contracts.
Four meters run on top of the seats, and each one grows with the project rather than the headcount:
- Model builds past your plan’s monthly allowance, billed as overage. dbt Labs no longer publishes the per-model rate, so ask for your number before you size the schedule.
- Semantic Layer queried metrics, 5,000 a month on Starter and 20,000 on Enterprise.
- dbt State, at $0.094 per daily active target table.
- dbt Wizard tokens, at each model provider’s rate, unless you bring your own key.
Our dbt pricing breakdown works a five-person team with 400 models through the full bill: about $2,400 a month with dbt State on, roughly $710 with it off. The seats are the predictable line. The meters are the one that moves when somebody adds a model or schedules another job.
There is also an indirect cost. dbt Cloud covers transformation and scheduling, and it does not cover orchestration of the broader pipeline. Teams still need to run and maintain Airflow or another orchestrator alongside it, which means the dbt Cloud platform cost is only part of the picture.
Managed dbt
Datacoves provides the full environment: VS Code, dbt Core, Airflow, CI/CD, secrets management, documentation hosting, and governance guardrails. There is no separate orchestration bill, no environment infrastructure to maintain, and no platform engineering team required to keep it running.
Onboarding a new developer takes minutes, not days. Datacoves customers report reducing onboarding time by approximately 30 hours per developer. At scale, across a team of 20 or 30 engineers, that compounds quickly.
The right comparison is not Datacoves versus dbt Cloud’s license fee. It is Datacoves versus the total cost of dbt Cloud plus Airflow infrastructure plus the engineering time to build and maintain the environment around them.
dbt on Snowflake
Snowflake runs dbt natively, which adds a platform option that didn’t exist when this comparison was only dbt Core against dbt Cloud. dbt Projects on Snowflake reached general availability in November 2025. You develop in the Workspaces editor in Snowsight or in CoCo Desktop, deploy a project folder as a schema-level object, and schedule runs with Snowflake tasks or with Airflow. Snowflake provides managed dbt Core and dbt Fusion runtimes, and you can pin a version or set an account-level default.
The pricing is the part worth knowing first. Snowflake’s documentation states that executions use a virtual warehouse and incur standard compute costs, with no additional Snowflake licensing or per-user fees. For a team already paying for Snowflake compute, that takes the seat line out of the budget.
Budget for two warehouses per run, though, not one. The session that issues EXECUTE DBT PROJECT runs on one warehouse and the target in profiles.yml runs on another, and Snowflake bills each for the time it is active. Snowflake’s best-practice guidance is to keep the task’s warehouse and the profile’s warehouse the same so one run doesn’t wake both.
Three constraints are worth checking before you commit a large project, all of them from Snowflake’s own limitations page. The adapter has to be snowflake, so this is a single-warehouse answer by design. Serverless tasks can’t execute dbt project objects, so every scheduled run needs a user-managed warehouse. And a deployed project folder caps at 100,000 files, the DAG view renders 300 models at a time, and stdout appears only once a command finishes.
Scope is the larger question. dbt on Snowflake covers the dbt stage of the pipeline well. It doesn’t cover ingestion, the Python and ML workloads that run beside your models, or any step that has to reach a self-hosted GitLab, an on-premises database, or an internal API behind your firewall. Teams with those requirements run Airflow alongside it, which puts them back where this comparison started. Running both as one managed environment against Snowflake is what our Snowflake integration is.
For the practitioner’s path, see our guide to setting up dbt with Snowflake, and for what a platform needs beyond the warehouse, Snowflake Won’t Build Your Data Platform For You.
Managed dbt: SaaS or Your Own Cloud
Four platform options is a lot for a decision that used to be two.
dbt Core gives you full control and zero license cost, and leaves your team to build and run the platform itself. dbt Cloud removes that burden, and constrains your tooling, your security posture, and your budget as you scale. dbt on Snowflake removes it for the Snowflake-shaped part of your pipeline and leaves the rest to you. A managed dbt platform takes the whole platform off your team and leaves you the choice of where it runs.
A managed dbt platform provides the operational simplicity of dbt Cloud with the flexibility and security of dbt Core, as SaaS or deployed in your own cloud.
Datacoves delivers the operational simplicity of dbt Cloud without the vendor lock-in or the platform constraints. It runs as SaaS, or inside your own AWS, Azure, or GCP account when your requirements call for that. Either way your team gets a fully configured environment from day one: VS Code in the browser, dbt Core, Managed Airflow, CI/CD pipelines, secrets management, and governance guardrails.
You keep full ownership of your code and your data. You choose your warehouse, your Git provider, your CI tool, your LLM, and your BI stack. When your requirements change, the platform adapts. There is no migration to a new vendor and no renegotiation of what the platform will and will not support.
For enterprise teams in regulated industries, for organizations that have outgrown dbt Cloud’s constraints, and for data leaders who want the best-practice foundation of a managed platform without surrendering control, Datacoves is the path that does not require a compromise.
Datacoves doesn’t replace your tools. It gives them a proper home.
How to Choose: dbt Core vs dbt Cloud vs Managed dbt
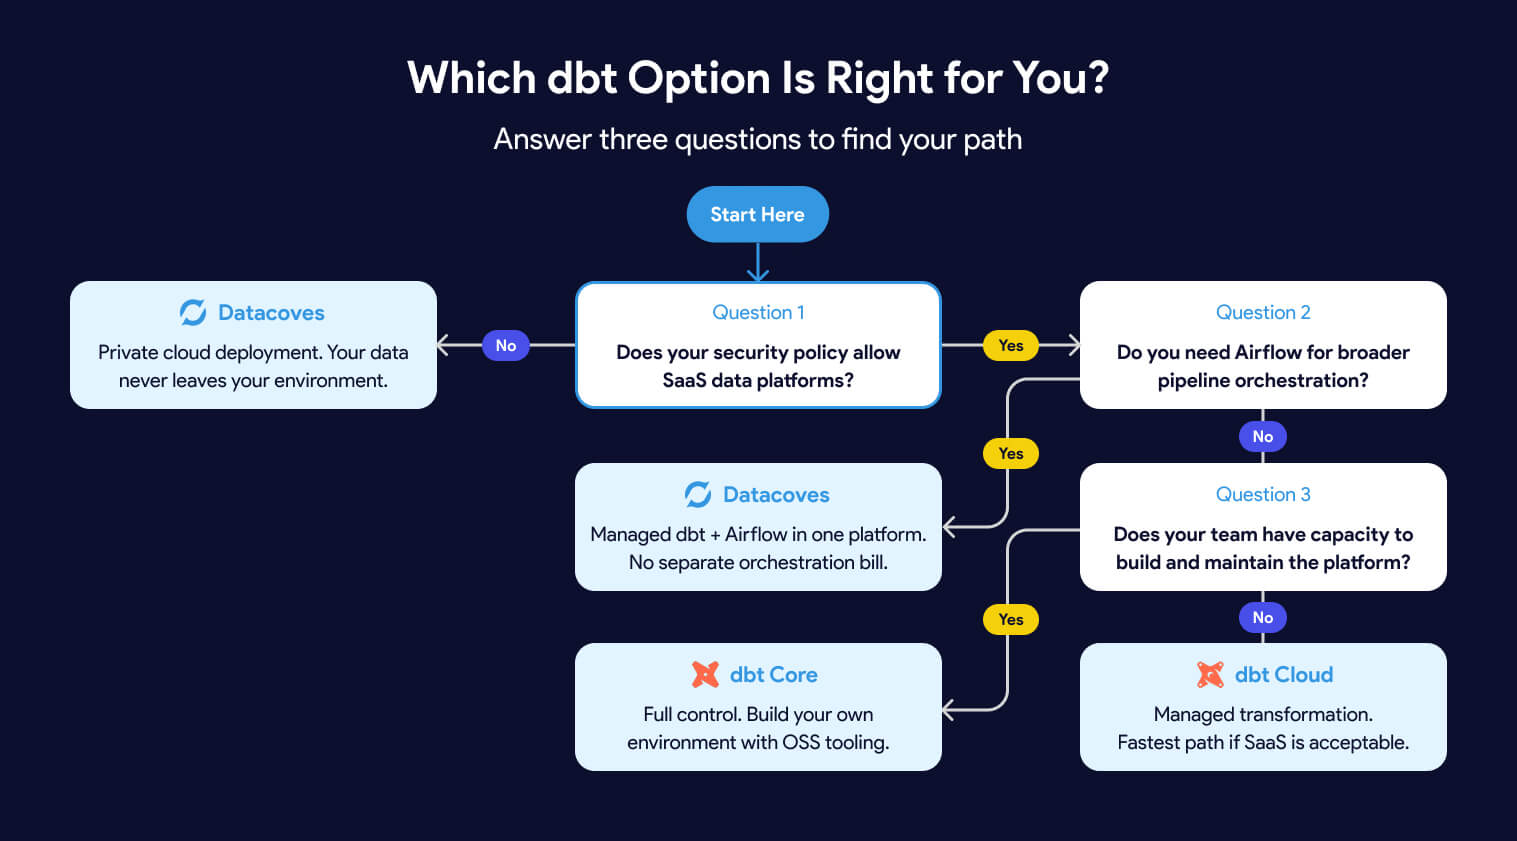
The right choice depends on your team’s size, security requirements, and how much of the platform you want to own.
Choose dbt Core if:
- You have a small, highly technical team that is comfortable building and maintaining infrastructure
- You want complete control over every component of your stack
- You have existing Airflow infrastructure and the engineering capacity to integrate it properly
- Budget is the primary constraint and you can absorb the hidden costs of DIY
Choose dbt Cloud if:
- Your security and compliance requirements allow for SaaS-based code and metadata hosting
- You want a fully managed transformation environment without standing up your own infrastructure
- Your orchestration needs are met by dbt’s built-in scheduler and you do not need Airflow
- Your team is five developers or fewer on one project, or you have budget for an Enterprise contract
- dbt Wizard’s managed model list covers the provider your security team approved, or you can bring your own key
- You are just getting started with dbt and that is your only priority right now
Choose dbt on Snowflake if:
- Snowflake is your only warehouse and you expect it to stay that way
- Your pipeline starts and ends in Snowflake, with no ingestion or activation steps that need a general-purpose orchestrator
- You want dbt runs on the compute bill you already pay, with no seat licenses
- Your Git provider and CI are supported, and nothing in the pipeline sits behind a firewall Snowflake can’t reach
Choose Datacoves if:
- You are in a regulated industry where data and code must stay inside your own cloud
- You have outgrown dbt Cloud’s constraints around Git providers, CI tooling, or orchestration
- You need managed Airflow alongside dbt without building and maintaining the integration yourself
- You want any approved copilot and any MCP server in the IDE, with no AI metering on the platform bill
- You are modernizing from legacy ETL and need a proven architecture with best practices built in
- You want the operational simplicity of a managed platform without surrendering control of your environment
If you are evaluating dbt Core and dbt Cloud and neither feels quite right, that is usually a signal. Most enterprise teams do not lack good tools. They lack a proper platform to run them in. Our Data Platform Evaluation Worksheet is there if you want to structure that comparison before you commit.
Ready to see how Datacoves works in your environment?
Book a demo to walk through the platform with a Datacoves expert.